
 Contact
 Hoe winkelen bij ons werkt

Bezorging
Winkelgids
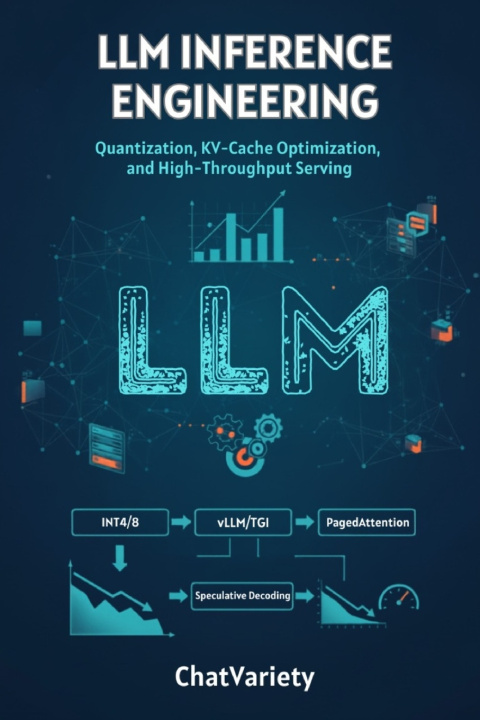
LLM Inference Engineering
Quantization, KV-Cache Optimization, and High-Throughput Serving: A Production Engineer's Guide to INT4/INT8 Quantization, vLLM, TGI, Speculative Decoding, and Cost Optimization
 Engels
 26 b
Tot 30 dagen retourrecht
Dit vind je misschien ook interessant


Master the Art of Low-Latency, High-Throughput LLM Serving
In 2026, the defining challenge of production AI is no longer training-it is cost-effective inference. LLM Inference Engineering is the definitive production guide for software engineers, ML developers, and DevOps professionals tasked with deploying large language models at scale without breaking the bank.
This hands-on manual strips away the theoretical academic jargon and delivers practical, production-ready strategies to cut your GPU and cloud serving costs by 50% to 70% while maintaining absolute response quality.
What You Will Master:- Advanced Quantization: Hands-on implementation of INT4/INT8 quantization using AWQ, GPTQ, and GGUF algorithms without destroying model accuracy.
- High-Throughput Architectures: Deep dives into PagedAttention, continuous batching, and GPU memory management to maximize hardware utilization.
- Serving Frameworks: Configuration recipes and production tuning guidelines for vLLM, TGI (Text Generation Inference), and llama.cpp.
- Speed Optimization: Implement speculative decoding to achieve 2x to 4x latency reduction with mathematically guaranteed quality.
- Scaling to 70B+ Models: Configure multi-GPU setups using tensor parallelism to distribute memory footprints efficiently.
- Rigorous Benchmarking: Establish robust metrics for latency, cost-per-token, and throughput to justify infrastructure decisions.
Written specifically for practicing engineers, this guide assumes familiarity with Python and basic PyTorch. Inside, you will find real-world deployment examples, benchmarking code, and architectural breakdowns that bridge the gap between model training and highly scalable production deployments. Equip yourself with the skills to architect the next generation of AI infrastructure. Stop wasting expensive GPU cycles-optimize your inference pipeline today.


Informatie over het boek
Engels

Geef dit boek vandaag nog cadeau
Dat gaat heel eenvoudig
1 Voeg het boek toe aan je winkelwagentje en selecteer Als cadeau bezorgen 2 Je krijgt van ons per omgaand een voucher 3 Het boek wordt bezorgd op het adres van de ontvangerHoi! Ik ben Libroamiko, je boekadviseur.
Hoe kan ik je helpen?